| Publication number | US20120191694A1 |
| Official title | Generation of topic-based language models for an app search engine |
| Assignee | Apple Inc. |
| Inventors | Natalia Hernandez Gardiol, Catherine Anne Edwards |
| Priority date | December 9, 2010 |
| Filed | April 5, 2012 |
| Published | July 26, 2012 |
| Granted as | US9805022B2, October 31, 2017 |
| Status | Expired, fee related |
| Family | US9805022B2, WO2012154348A1, PCT/US2012/032589, TW101112160A |
| Source | patents.google.com/patent/US20120191694A1 |
What This Patent Covers and Why It Matters for ASO
Feature it describes: functional app search, meaning the ability to find an app by what it does rather than by its name.
This is the earliest and, in some ways, the most foundational document in this collection. Its opening premise is a statement about how bad app store search was in 2010: existing stores let users search only by application name or developer. The patent’s purpose is to make it possible to search by function.
The method is topic modeling. The system assembles a corpus from app names, app descriptions and external sources such as app review websites, cleans it, runs Latent Dirichlet Allocation to discover groups of words that co-occur, and builds a language model per app from the resulting topics. It then does something that should stop any ASO practitioner mid sentence: it mines search logs to find which query terms preceded downloads of each app, and adds those terms to the app’s language model even when they do not appear in the app’s own description.
The patent’s example is Yelp. The word “food” might not appear in Yelp’s description, but search logs show that users who search “restaurant” frequently download Yelp, so “food” gets added to Yelp’s model anyway.
What follows for practice:
- Your app can rank for terms you never wrote, earned through conversion rather than metadata. This is the oldest and clearest statement of that mechanism in Apple’s portfolio.
- The corpus includes external sources. Reviews and commentary on app review websites are named as inputs, which makes earned coverage a potential input to how the store understands your app, not only a traffic source.
- Words are canonicalized before modeling, with “text”, “texting” and “texts” given as variants grouped together. Keyword plurals and inflections are being collapsed at the indexing stage, so spending distinct keyword slots on them is spending twice for one signal.
- A post processing step keeps only topic words that actually appear in the official materials, before the search log terms are added back. Your description therefore acts as a filter on which discovered topics you are allowed to keep.
- Human reviewers remove poor quality topics. Manual curation was part of the original design, which is worth remembering before assuming everything in app search is fully automated.
Patent Summary
“Topic-based language models for an application search engine enable a user to search for an application based on the application’s function rather than title. To enable a search based on function, information is gathered and processed, including application names, descriptions and external information. Processing the information includes filtering the information, generating a topic model and supplementing the topic model with additional information.”
US20120191694A1, abstract
Claim 1 as filed is strikingly broad and short: analyzing a description of a mobile device application, processing that description into processed information, and generating a topic based language model for a mobile device application search from the processed information. Everything that makes the invention interesting, the corpus composition, the LDA step, the human filtering and the search log supplementation, sits in the specification rather than in the independent claim.
Detailed Explanation
The dates, and what they suggest
Three dates sit oddly together and are worth laying out plainly.
| Date | Event |
|---|---|
| December 9, 2010 | Priority date |
| February 2012 | Apple acquires Chomp, an app search engine |
| April 5, 2012 | This application filed, assigned to Apple |
| July 26, 2012 | Published |
| October 31, 2017 | Granted as US9805022B2 |
A priority date fourteen months before the acquisition, a filing two months after it, an assignment to Apple, and the phrase “app search engine” in the title. The two named inventors then go on to author Apple’s central app search filings: Catherine Anne Edwards and Natalia Hernandez Gardiol appear together on US9405832B2, the query classifier, and on US9280595B2, concept matching.
The pattern is consistent with work that originated outside Apple and arrived with an acquisition, then continued inside it. That is an inference from public dates and names, not something either document states, and it should be read as a hypothesis. What is not in question is that this filing is the earliest in the sequence and that the same two people carried the line forward for years afterward.
The pipeline, step by step
Figure 1 of the patent sets out the whole indexing process as a single flow. The numbered steps are worth reading in order, because each one constrains what your metadata can achieve.
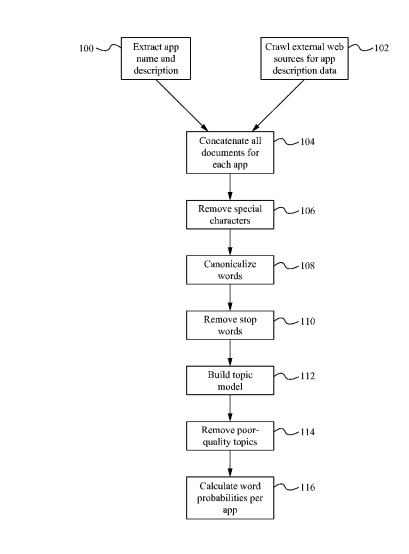
- Extract app name and description (100)
- Crawl external web sources for app description data (102)
- Concatenate all documents for each app (104)
- Remove special characters (106)
- Canonicalize words (108)
- Remove stop words (110)
- Build topic model (112)
- Remove poor quality topics (114)
- Calculate word probabilities per app (116)
Note step 102. The patent says crawl, which settles any doubt about whether external sources are a passive option or an active part of the pipeline.
What a topic based language model is
A language model, here, is a set of topics attached to an app, where each topic is a group of words with probability values expressing how strongly each word belongs.
The patent’s worked example is a to do list app. Its model contains several topics at once: a to do topic, a calendar topic, and a user interface topic. A word such as “task” draws high association values from more than one topic. Interface words such as “swipe”, “tap” and “zoom” gain strength through the interface topic.
Two things follow. An app is not assigned one subject, it carries a mixture, which is how a productivity app can be findable through calendar vocabulary without claiming to be a calendar. And interface vocabulary forms its own topic, meaning the way you describe interacting with the app contributes to its model separately from what the app is for.
The corpus
The corpus is assembled from two kinds of source, concatenated into unified documents.
- Store metadata: official app names and descriptions, with iTunes and the Android Market both named
- External web sources: reviews and commentary from dedicated app review websites
That the design contemplates both major stores is a detail worth noting. This was built as an app search engine across catalogs, not as an Apple store feature, which fits the acquisition hypothesis above.
The external sources matter more for ASO. If third party review coverage is part of the corpus that defines an app’s topics, then the vocabulary journalists and reviewers use about your app feeds into how it is understood. You cannot write that copy, but you can influence it through how you brief and position the product.
Cleaning, and why canonicalization matters to you
Before modeling, the corpus is cleaned: special characters and HTML tags are stripped, words are canonicalized so that variants group together, and stop words such as “a”, “the” and “and” are removed.
The canonicalization example given is “text”, “texting” and “texts” treated as variants of one word. For anyone filling a 100 character keyword field, this is the practical answer to a perennial question. If inflections collapse to one canonical form at indexing, then including both the singular and the plural buys nothing. The same logic applies to the verb and noun forms of the same root.
Treat it as a strong hint rather than a rule about today’s App Store, since this is a 2010 priority document describing a system that may or may not be the current indexer. But it is direct evidence about how Apple’s own app search engineers approached the question.
How topics are generated
Topics come from Latent Dirichlet Allocation, a standard technique that finds groups of words that frequently co-occur across documents without being told what to look for. The patent’s illustration is a topic containing “food”, “eat”, “restaurant” and “nearby”.
The system generates roughly ten topics from the corpus and calculates probabilities for how frequently each topic appears across documents. Topics recurring across several documents score higher than topics appearing once.
Then human reviewers filter the output, removing poor quality topics that do not meaningfully represent app functionality. LDA reliably produces some junk topics, so this step is expected engineering practice rather than a weakness, but it does mean the topic vocabulary was curated by people.
Post processing, in two moves
This is the part with the most practical content, and it runs in two opposing directions.
First, subtraction. The generated topic words are compared against the app’s original description, and only words actually present in the official materials are retained. Topic modeling is generous, and this step reins it in. Your description acts as a whitelist: a topic can only contribute vocabulary you actually used.
Then, addition. Search logs are analyzed to identify the query terms users entered before downloading each specific app, and those terms are added to the app’s language model. This is where the Yelp example lands. If users search “restaurant” and download Yelp, the association becomes part of Yelp’s model, and “food” can be added manually or automatically even though it never appears in Yelp’s description.
Put the two moves together and the shape of the system is clear. Your own text determines which discovered vocabulary you keep. User behavior determines which vocabulary you gain beyond it. The first is under your control and bounded. The second is unbounded and earned.
What this means for the keyword field
- Write descriptions that use the full ordinary vocabulary of the problem your app solves, because the subtraction step means unused words cannot help you even when the topic model discovers them.
- Do not spend slots on plurals and inflections of the same root if canonicalization is in play.
- Treat conversion on a query as the only route to vocabulary you did not write. There is no metadata trick that substitutes for it.
- Describe the interaction as well as the purpose, since interface vocabulary forms its own topic in the worked example.
Status and family
The application granted as US9805022B2 in October 2017, almost seven years after its priority date, and has since expired for unpaid maintenance fees. The family includes an international filing, PCT/US2012/032589, published as WO2012154348A1, and a Taiwanese filing.
A seven year prosecution is long, and the extremely broad claim 1 in the published application is a likely reason. Broad claims invite prior art rejections, and topic modeling for search was not new in 2010. What is specific to this filing is the combination: an app corpus extended with external review sources, curated topics, description filtering, and search log supplementation.
Related patents on this site
US9280595B2 is the direct descendant of this idea, replacing topic models with indicator terms derived from co-occurrence and download behavior. US9405832B2 adds the decision about what kind of query is being asked.
Bir yanıt yazın